diff --git a/.forgejo/workflows/docs.yml b/.forgejo/workflows/docs.yml
index 7ad8502..2d636a6 100644
--- a/.forgejo/workflows/docs.yml
+++ b/.forgejo/workflows/docs.yml
@@ -1,4 +1,4 @@
-name: Publish documentation
+name: Publish documentation to great-ai.schmelczer.dev
on:
push:
@@ -9,10 +9,18 @@ on:
- 'mkdocs.yaml'
- 'pyproject.toml'
- '.forgejo/workflows/docs.yml'
+ pull_request:
+ branches: [main]
+ paths:
+ - 'docs/**'
+ - 'great_ai/**'
+ - 'mkdocs.yaml'
+ - 'pyproject.toml'
+ - '.forgejo/workflows/docs.yml'
workflow_dispatch:
concurrency:
- group: pages
+ group: docs-${{ github.ref }}
cancel-in-progress: false
jobs:
@@ -42,11 +50,10 @@ jobs:
. .venv/bin/activate
mkdocs build
- # The old workflow ran `mkdocs gh-deploy` (GitHub Pages); on this instance
- # built sites are rsynced into the host /pages mount that nginx serves,
- # via the shared ci-actions/deploy-pages action — same as photos/reconcile.
- - name: Deploy to pages mount
- if: github.ref == 'refs/heads/main'
+ # As in reconcile, publish through the shared action to /pages/great-ai,
+ # served at https://great-ai.schmelczer.dev.
+ - name: Deploy to great-ai.schmelczer.dev
+ if: (github.event_name == 'push' || github.event_name == 'workflow_dispatch') && github.ref == 'refs/heads/main'
uses: http://forgejo:3000/andras/ci-actions/deploy-pages@main
with:
source: site
diff --git a/Dockerfile b/Dockerfile
index 260b0a6..61335a2 100644
--- a/Dockerfile
+++ b/Dockerfile
@@ -36,7 +36,7 @@ from great_ai import GreatAI
\
@GreatAI.create
def hello_world(name: str) -> str:
- """Learn more about GreatAI at https://great-ai.scoutinscience.com"""
+ """Learn more about GreatAI at https://great-ai.schmelczer.dev"""
return f"Hello {name}!"
EOF
diff --git a/README.md b/README.md
index 6c3bce8..39868c5 100644
--- a/README.md
+++ b/README.md
@@ -39,7 +39,7 @@ That's it. Your GreatAI service is _nearly_ ready for production use. Many of th
Before production, replace the default local TinyDB tracing database with a production-suitable backend, configure storage and deployment infrastructure, and review the remaining best practices for your use case.
-> **Published documentation:** [Read the rendered guides, API reference, and notebooks](https://great-ai.scoutinscience.com). The files under `docs/` use MkDocs features that repository previews may not render.
+> **Published documentation:** [Read the rendered guides, API reference, and notebooks](https://great-ai.schmelczer.dev). The files under `docs/` use MkDocs features that repository previews may not render.
## Why is this GREAT?
@@ -57,11 +57,11 @@ GreatAI fits between the prototype and deployment phases of your AI development
There are other existing solutions aiming to facilitate this phase. [Amazon SageMaker](https://aws.amazon.com/sagemaker) and [Seldon Core](https://docs.seldon.ai/seldon-core-2) provide the most comprehensive suite of features. If you have the opportunity to use them, do that because they're great.
-However, [research indicates](https://great-ai.scoutinscience.com) that professionals rarely use them. This may be due to their inherent setup and operational complexity. **GreatAI is designed to be as simple to use as possible.** Its straightforward, high-level API and sensible default configuration make it easy to start using. Despite its relative simplicity over Seldon Core, it still implements many of the [SE4ML best practices](https://se-ml.github.io), and thus, can meaningfully improve your deployment without requiring prohibitively great effort.
+However, [research indicates](https://great-ai.schmelczer.dev) that professionals rarely use them. This may be due to their inherent setup and operational complexity. **GreatAI is designed to be as simple to use as possible.** Its straightforward, high-level API and sensible default configuration make it easy to start using. Despite its relative simplicity over Seldon Core, it still implements many of the [SE4ML best practices](https://se-ml.github.io), and thus, can meaningfully improve your deployment without requiring prohibitively great effort.
-## [Learn more](https://great-ai.scoutinscience.com)
+## [Learn more](https://great-ai.schmelczer.dev)
-[Check out the full documentation here](https://great-ai.scoutinscience.com).
+[Check out the full documentation here](https://great-ai.schmelczer.dev).
## Find `great-ai` on [PyPI](https://pypi.org/project/great-ai/)
diff --git a/docs/CNAME b/docs/CNAME
deleted file mode 100644
index 10425a6..0000000
--- a/docs/CNAME
+++ /dev/null
@@ -1 +0,0 @@
-great-ai.scoutinscience.com
\ No newline at end of file
diff --git a/docs/examples/scibert/deploy.ipynb b/docs/examples/scibert/deploy.ipynb
index 4f1363b..dd0f0b1 100644
--- a/docs/examples/scibert/deploy.ipynb
+++ b/docs/examples/scibert/deploy.ipynb
@@ -272,7 +272,7 @@
"metadata": {},
"source": [
"In this case, the service is built as a docker image, pushed to our image registry and subsequent rolling update is performed in the production cluster.\n",
- "To check out the Dockerimage, go to [the additional files page](https://great-ai.scoutinscience.com/examples/scibert/additional-files)."
+ "To check out the Dockerimage, go to [the additional files page](https://great-ai.schmelczer.dev/examples/scibert/additional-files)."
]
}
],
diff --git a/docs/examples/scibert/index.md b/docs/examples/scibert/index.md
index 8a5cd0f..56470f6 100644
--- a/docs/examples/scibert/index.md
+++ b/docs/examples/scibert/index.md
@@ -7,8 +7,8 @@ This is a simplified example illustrating how `great-ai` is used in practice at
## Objectives
-1. You will see how the [great_ai.utilities](https://great-ai.scoutinscience.com/reference/utilities) can integrate into your Data Science workflow.
-2. You will see how [great_ai.large_file](https://great-ai.scoutinscience.com/reference/large-file) can be used to version and store your trained model.
+1. You will see how the [great_ai.utilities](https://great-ai.schmelczer.dev/reference/utilities) can integrate into your Data Science workflow.
+2. You will see how [great_ai.large_file](https://great-ai.schmelczer.dev/reference/large-file) can be used to version and store your trained model.
3. You will see how [GreatAI][great_ai.GreatAI] should be used to prepare your model for a robust and responsible deployment.
4. You will see multiple ways of customising your deployment.
@@ -37,13 +37,13 @@ We load and analyse the data by calculating inter-rater reliability and checking
We simply fine-tune SciBERT.
-After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](https://great-ai.scoutinscience.com/how-to-guides/configure-service).
+After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](https://great-ai.schmelczer.dev/how-to-guides/configure-service).
### [Deployment notebook](deploy.ipynb)
We customise the GreatAI configuration, create custom caching for the model and implement an inference function that can be hardened by wrapping it in a [GreatAI][great_ai.GreatAI] instance. We also extract the attention weights as a quasi-explanation.
-Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](https://great-ai.scoutinscience.com/how-to-guides/use-service)
+Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](https://great-ai.schmelczer.dev/how-to-guides/use-service)
#### [Additional files](additional-files.md)
diff --git a/docs/examples/scibert/train.ipynb b/docs/examples/scibert/train.ipynb
index 07c81d8..a39fad3 100644
--- a/docs/examples/scibert/train.ipynb
+++ b/docs/examples/scibert/train.ipynb
@@ -348,7 +348,7 @@
"id": "cell-8",
"metadata": {},
"source": [
- "The [saved historical run](https://great-ai.scoutinscience.com/examples/scibert/validation-results.json) selected a checkpoint with **validation binary F1 of 0.8966** (recorded value: 0.896551724137931). This validation split was also used for early stopping and checkpoint selection, so the number is not an independent test result or macro F1. The historical split seed was not recorded; the seeded code above defines future runs and does not reproduce that split. Its results are saved to `models/validation_results.json` and `models/validation-run.json`.\n",
+ "The [saved historical run](https://great-ai.schmelczer.dev/examples/scibert/validation-results.json) selected a checkpoint with **validation binary F1 of 0.8966** (recorded value: 0.896551724137931). This validation split was also used for early stopping and checkpoint selection, so the number is not an independent test result or macro F1. The historical split seed was not recorded; the seeded code above defines future runs and does not reproduce that split. Its results are saved to `models/validation_results.json` and `models/validation-run.json`.\n",
"\n",
"To estimate performance after model selection, evaluate once on a separate untouched test split. We make no test-set performance claim here. Next, store the selected model for deployment."
]
@@ -409,7 +409,7 @@
"id": "cell-10",
"metadata": {},
"source": [
- "Next: [Part 3](https://great-ai.scoutinscience.com/examples/scibert/deploy)"
+ "Next: [Part 3](https://great-ai.schmelczer.dev/examples/scibert/deploy)"
]
}
],
diff --git a/docs/examples/simple/data.ipynb b/docs/examples/simple/data.ipynb
index 3a048d3..4d0b397 100644
--- a/docs/examples/simple/data.ipynb
+++ b/docs/examples/simple/data.ipynb
@@ -185,7 +185,7 @@
"id": "cell-10",
"metadata": {},
"source": [
- "### Next: [Part 2](https://great-ai.scoutinscience.com/examples/simple/train)"
+ "### Next: [Part 2](https://great-ai.schmelczer.dev/examples/simple/train)"
]
}
],
diff --git a/docs/examples/simple/deploy.ipynb b/docs/examples/simple/deploy.ipynb
index a7a57a7..5981f57 100644
--- a/docs/examples/simple/deploy.ipynb
+++ b/docs/examples/simple/deploy.ipynb
@@ -9,10 +9,10 @@
"\n",
"> Part 3: Create production inference function\n",
"\n",
- "\n",
+ "\n",
"> The blue boxes show the steps implemented in this notebook.\n",
"\n",
- "In [Part 2](https://great-ai.scoutinscience.com/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
+ "In [Part 2](https://great-ai.schmelczer.dev/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
"\n",
"## Create the inference function\n",
"\n",
diff --git a/docs/examples/simple/train.ipynb b/docs/examples/simple/train.ipynb
index 2b328a0..bdc62ff 100644
--- a/docs/examples/simple/train.ipynb
+++ b/docs/examples/simple/train.ipynb
@@ -7,14 +7,14 @@
"source": [
"# Optimise and train a model\n",
"\n",
- "\n",
+ "\n",
"> The blue boxes show the steps implemented in this notebook.\n",
"\n",
"Run `data.ipynb` first. We read its ground truth from the shared local TinyDB database. The default uses a compact parameter search suitable for the bundled sample; `GREAT_AI_NOTEBOOK_FULL=1` enables the original larger search on the full MAG training data. \n",
"\n",
"In this part, we hyperparameter-optimise and train a simple Naive Bayes classifier which we then export for deployment using `great_ai.save_model`.\n",
"\n",
- "## Load data that has been extracted in [part 1](https://great-ai.scoutinscience.com/examples/simple/data)"
+ "## Load data that has been extracted in [part 1](https://great-ai.schmelczer.dev/examples/simple/data)"
]
},
{
@@ -138,7 +138,7 @@
"\n",
"Each paper may have several accepted labels. We expand it into one training row per label for this single-label classifier, but keep all rows with the same paper text in one cross-validation fold using `GroupKFold`. The final train/test split was already made by paper in Part 1, before expansion.\n",
"\n",
- "The search uses macro F1 on the expanded single-label validation rows as a training surrogate. This differs from the top-1 hit rate and fixed-target multilabel metrics used to evaluate the deployed label sets in [Part 3](https://great-ai.scoutinscience.com/examples/simple/deploy). Rerun the search to obtain results for these grouped folds; the previous ungrouped outputs have been removed."
+ "The search uses macro F1 on the expanded single-label validation rows as a training surrogate. This differs from the top-1 hit rate and fixed-target multilabel metrics used to evaluate the deployed label sets in [Part 3](https://great-ai.schmelczer.dev/examples/simple/deploy). Rerun the search to obtain results for these grouped folds; the previous ungrouped outputs have been removed."
]
},
{
@@ -2783,7 +2783,7 @@
"id": "cell-11",
"metadata": {},
"source": [
- "## Next: [Part 3](https://great-ai.scoutinscience.com/examples/simple/deploy)"
+ "## Next: [Part 3](https://great-ai.schmelczer.dev/examples/simple/deploy)"
]
}
],
diff --git a/docs/how-to-guides/call-remote.md b/docs/how-to-guides/call-remote.md
index 325175b..3912ad1 100644
--- a/docs/how-to-guides/call-remote.md
+++ b/docs/how-to-guides/call-remote.md
@@ -22,7 +22,7 @@ async def slow_greeter(your_name):
await sleep(2)
return f'Hi {your_name}!'
```
-> Run this in development mode by executing `great-ai server.py` or `python3 -m great_ai server.py` if you're on Windows and [`great-ai` is not in your `PATH`](https://great-ai.scoutinscience.com/how-to-guides/install).
+> Run this in development mode by executing `great-ai server.py` or `python3 -m great_ai server.py` if you're on Windows and [`great-ai` is not in your `PATH`](https://great-ai.schmelczer.dev/how-to-guides/install).
### Client
@@ -48,7 +48,7 @@ print(results)
> Run this script as a regular Python script by executing `python3 client.py`.
-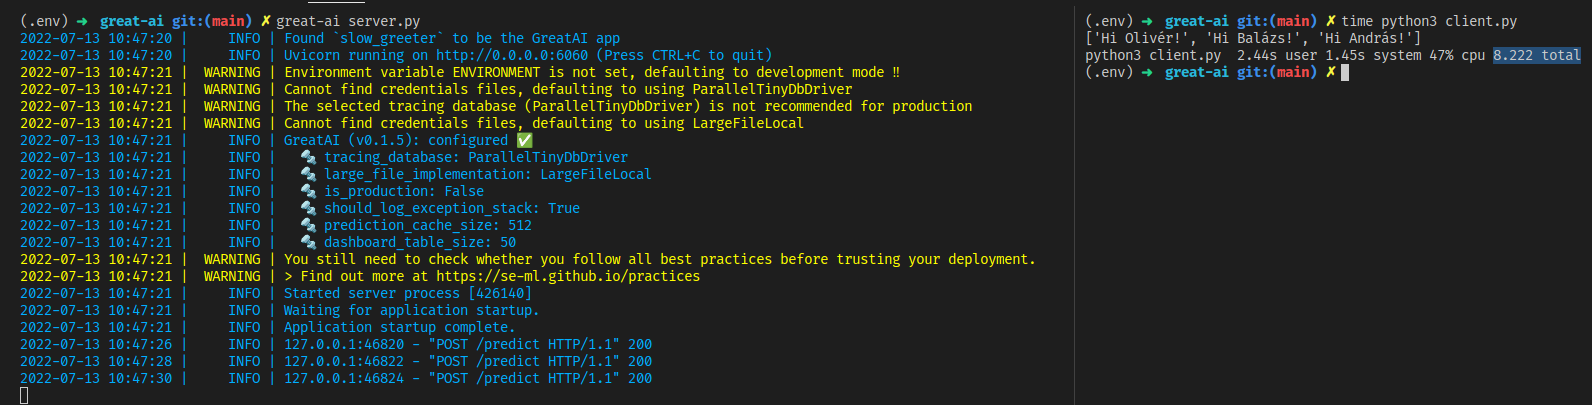{ loading=lazy }
+{ loading=lazy }
As you can see, everything worked as expected. There is one way to improve it, though.
## An `async` example
@@ -86,6 +86,6 @@ asyncio.run(main())
> Replace `client.py` with this async client. Note that although async support is significantly more streamlined in recent Python versions, it still requires a bit more boilerplate than its synchronous counterpart.
-{ loading=lazy }
+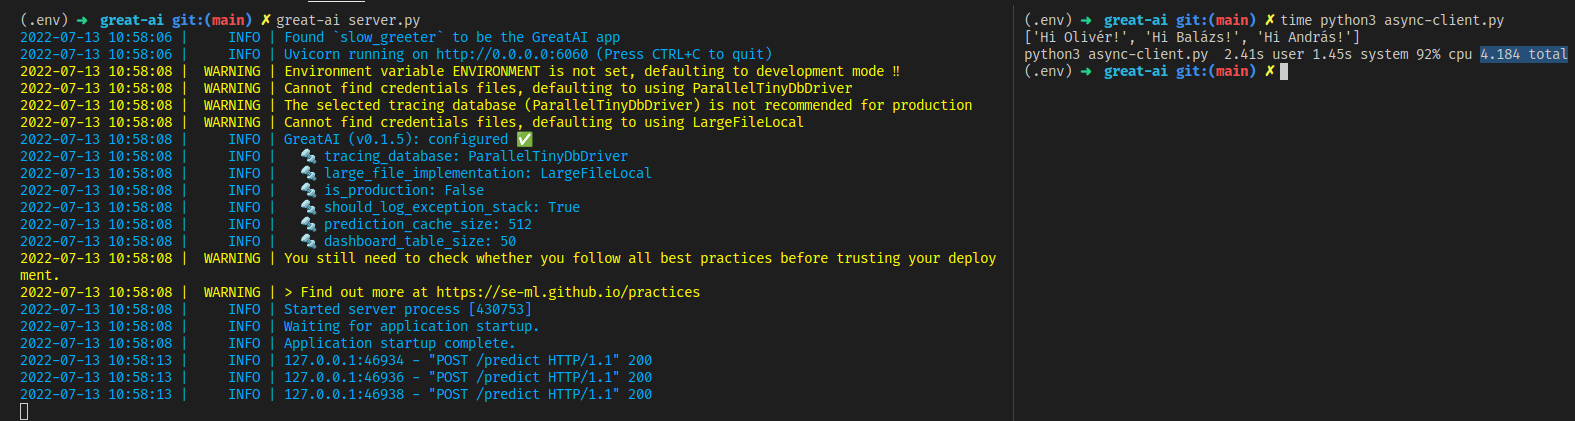{ loading=lazy }
This also works and might be considerably quicker in some use cases.
diff --git a/docs/how-to-guides/create-service.md b/docs/how-to-guides/create-service.md
index 05f0f92..21cf026 100644
--- a/docs/how-to-guides/create-service.md
+++ b/docs/how-to-guides/create-service.md
@@ -38,7 +38,7 @@ This not only allows you to statically type-check your code, but by default, Gre
## With async
-Asynchronous code can result in immense performance gains in some instances. For example, you might rely on a third-party service, do database access, or [call a remote GreatAI instance](https://great-ai.scoutinscience.com/how-to-guides/call-remote). In these cases, you can make your function `async` without any other changes.
+Asynchronous code can result in immense performance gains in some instances. For example, you might rely on a third-party service, do database access, or [call a remote GreatAI instance](https://great-ai.schmelczer.dev/how-to-guides/call-remote). In these cases, you can make your function `async` without any other changes.
```python title="async_greeter.py"
from great_ai import GreatAI
@@ -117,4 +117,4 @@ def add_number(positive_number: int, secret: int) -> int:
assert add_number(1).output == 5
```
-1. Refer to [the configuration page](https://great-ai.scoutinscience.com/how-to-guides/configure-service) for specifying where to store your models.
+1. Refer to [the configuration page](https://great-ai.schmelczer.dev/how-to-guides/configure-service) for specifying where to store your models.
diff --git a/docs/how-to-guides/handle-training-data.md b/docs/how-to-guides/handle-training-data.md
index 76db2a6..2fafa35 100644
--- a/docs/how-to-guides/handle-training-data.md
+++ b/docs/how-to-guides/handle-training-data.md
@@ -60,7 +60,7 @@ After the initial data gathering, end-to-end feedback can also be integrated int
The scaffolded REST API contains endpoints for managing traces and their feedbacks.
-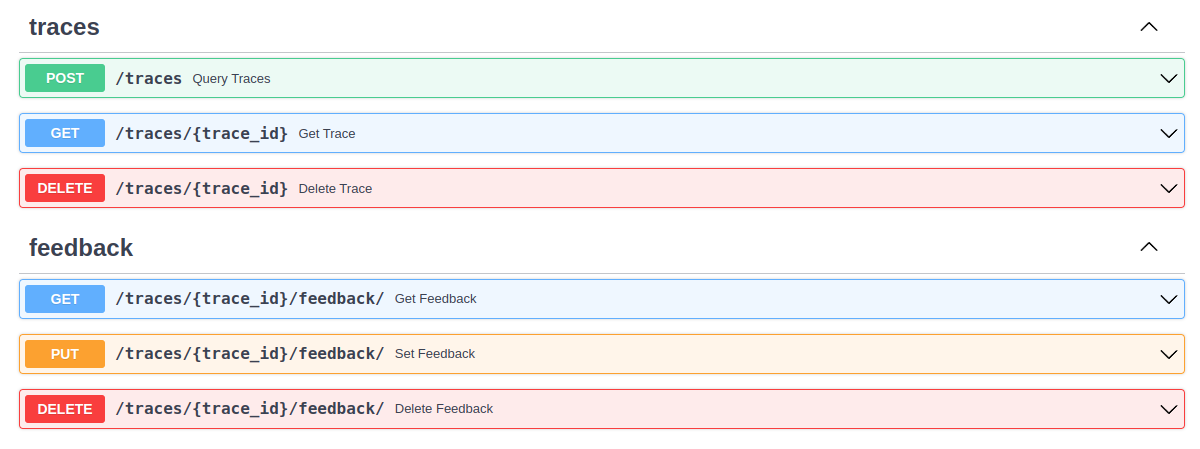{ loading=lazy }
+{ loading=lazy }
When [great_ai.query_ground_truth][] is executed, it implicitly filters for traces that have feedback. Therefore, both the `ground_truth` and the `online` traces that have received feedback are returned. No matter the origin of the data, it can be accessed using the same API.
diff --git a/docs/how-to-guides/large-file.md b/docs/how-to-guides/large-file.md
index 57ec672..9b2eefd 100644
--- a/docs/how-to-guides/large-file.md
+++ b/docs/how-to-guides/large-file.md
@@ -1,6 +1,6 @@
# How to use LargeFiles
-The functions [save_model][great_ai.use_model] and [@use_model][great_ai.use_model] wrap LargeFile instances. Hence, besides configuring [LargeFile](https://great-ai.scoutinscience.com/reference/large-file), users have few reasons to use LargeFiles directly.
+The functions [save_model][great_ai.use_model] and [@use_model][great_ai.use_model] wrap LargeFile instances. Hence, besides configuring [LargeFile](https://great-ai.schmelczer.dev/reference/large-file), users have few reasons to use LargeFiles directly.
## Motivation
diff --git a/docs/how-to-guides/use-service.md b/docs/how-to-guides/use-service.md
index 45f8003..de5bcef 100644
--- a/docs/how-to-guides/use-service.md
+++ b/docs/how-to-guides/use-service.md
@@ -1,6 +1,6 @@
# How to perform prediction with GreatAI
-After [creating a GreatAI service](https://great-ai.scoutinscience.com/how-to-guides/create-service) by wrapping your prediction function, and optionally [configuring it](https://great-ai.scoutinscience.com/how-to-guides/configure-service), it's time to do some prediction.
+After [creating a GreatAI service](https://great-ai.schmelczer.dev/how-to-guides/create-service) by wrapping your prediction function, and optionally [configuring it](https://great-ai.schmelczer.dev/how-to-guides/configure-service), it's time to do some prediction.
Let's take the following example:
@@ -107,7 +107,7 @@ COPY . .
CMD ["deploy.ipynb"]
```
-Create an `s3.ini` with the S3 keys described in the [configuration guide](https://great-ai.scoutinscience.com/how-to-guides/configure-service/#s3-compatible). Use concrete values in this build configuration: `ENV:` references are resolved inside the build container, which does not inherit your shell's environment. Replace `my-domain-predictor` with the key used when saving your model.
+Create an `s3.ini` with the S3 keys described in the [configuration guide](https://great-ai.schmelczer.dev/how-to-guides/configure-service/#s3-compatible). Use concrete values in this build configuration: `ENV:` references are resolved inside the build container, which does not inherit your shell's environment. Replace `my-domain-predictor` with the key used when saving your model.
Keep credentials and any local model cache out of `COPY . .` by adding these entries to your project's `.dockerignore`:
diff --git a/docs/index.md b/docs/index.md
index 4d036cf..7bb6433 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -88,7 +88,7 @@ great-ai demo.py
!!! success
Your GreatAI service is _nearly_ ready for production use. Many of the [SE4ML best practices](https://se-ml.github.io){ target=_blank } are configured and implemented automatically.
- Before production, replace the default local TinyDB tracing database with a production-suitable backend, [configure storage](https://great-ai.scoutinscience.com/how-to-guides/configure-service/) and [deployment infrastructure](https://great-ai.scoutinscience.com/how-to-guides/use-service/), and review the remaining best practices for your use case. Wrapping a function provides tracing and API scaffolding; model trustworthiness still requires use-case-specific evaluation and ongoing oversight.
+ Before production, replace the default local TinyDB tracing database with a production-suitable backend, [configure storage](https://great-ai.schmelczer.dev/how-to-guides/configure-service/) and [deployment infrastructure](https://great-ai.schmelczer.dev/how-to-guides/use-service/), and review the remaining best practices for your use case. Wrapping a function provides tracing and API scaffolding; model trustworthiness still requires use-case-specific evaluation and ongoing oversight.
## Why is this GREAT?
@@ -114,7 +114,7 @@ However, research indicates that professionals rarely use them. This may be due
[:fontawesome-brands-docker: Find it on DockerHub](https://hub.docker.com/repository/docker/schmelczera/great-ai){ .md-button .md-button--primary }
-[:fontawesome-solid-laptop-code: Check out the tutorial](https://great-ai.scoutinscience.com/tutorial){ .md-button .md-button--primary }
+[:fontawesome-solid-laptop-code: Check out the tutorial](https://great-ai.schmelczer.dev/tutorial){ .md-button .md-button--primary }
## Production use
diff --git a/docs/overrides/main.html b/docs/overrides/main.html
index 4b15dba..59a188a 100644
--- a/docs/overrides/main.html
+++ b/docs/overrides/main.html
@@ -6,7 +6,7 @@
-
+