Make documentation links usable from repository previews
This commit is contained in:

parent
34368bbe50
commit
e446d95855
17 changed files with 39 additions and 39 deletions
|
|
@ -6,7 +6,7 @@
|
|||
"source": [
|
||||
"# Explore data and feasibility of approach\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"We had asked our clients and in-house experts to annotate sentences using a rigorous guideline. The aim is to decide on which sentences they would like to see in a summary for a paper.\n",
|
||||
"\n",
|
||||
|
|
@ -276,7 +276,7 @@
|
|||
"source": [
|
||||
"We get an F1-score of 0.78 without any hyperparameter-optimisation; this task may be feasible to solve with AI.\n",
|
||||
"\n",
|
||||
"Next: [Part 2](/examples/scibert/train)"
|
||||
"Next: [Part 2](https://great-ai.scoutinscience.com/examples/scibert/train)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -290,7 +290,7 @@
|
|||
"metadata": {},
|
||||
"source": [
|
||||
"In this case, the service is built as a docker image, pushed to our image registry and subsequent rolling update is performed in the production cluster.\n",
|
||||
"To check out the Dockerimage, go to [the additional files page](/examples/scibert/additional-files)."
|
||||
"To check out the Dockerimage, go to [the additional files page](https://great-ai.scoutinscience.com/examples/scibert/additional-files)."
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -7,8 +7,8 @@ This is a simplified example illustrating how `great-ai` is used in practice at
|
|||
|
||||
## Objectives
|
||||
|
||||
1. You will see how the [great_ai.utilities](/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will see how [great_ai.large_file](/reference/large-file) can be used to version and store your trained model.
|
||||
1. You will see how the [great_ai.utilities](https://great-ai.scoutinscience.com/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will see how [great_ai.large_file](https://great-ai.scoutinscience.com/reference/large-file) can be used to version and store your trained model.
|
||||
3. You will see how [GreatAI][great_ai.GreatAI] should be used to prepare your model for a robust and responsible deployment.
|
||||
4. You will see multiple ways of customising your deployment.
|
||||
|
||||
|
|
@ -37,13 +37,13 @@ We load and analyse the data by calculating inter-rater reliability and checking
|
|||
|
||||
We simply fine-tune SciBERT.
|
||||
|
||||
After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](/how-to-guides/configure-service).
|
||||
After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](https://great-ai.scoutinscience.com/how-to-guides/configure-service).
|
||||
|
||||
### [Deployment notebook](deploy.ipynb)
|
||||
|
||||
We customise the GreatAI configuration, create custom caching for the model and implement an inference function that can be hardened by wrapping it in a [GreatAI][great_ai.GreatAI] instance. We also extract the attention weights as a quasi-explanation.
|
||||
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](/how-to-guides/use-service)
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](https://great-ai.scoutinscience.com/how-to-guides/use-service)
|
||||
|
||||
#### [Additional files](additional-files.md)
|
||||
|
||||
|
|
|
|||
|
|
@ -341,7 +341,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Next: [Part 3](/examples/scibert/deploy)"
|
||||
"Next: [Part 3](https://great-ai.scoutinscience.com/examples/scibert/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -8,10 +8,10 @@
|
|||
"\n",
|
||||
"Here, we solve a problem similar to the tutorial's but with an explainable Naive Bayes classifier and more best practices. In short, we train a domain classifier on the [semantic scholar dataset](https://api.semanticscholar.org/corpus) by taking full advantage of `great-ai`. Subsequently, we create a production-ready deployment.\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps of a typical AI-development lifecycle implemented in this notebook.\n",
|
||||
"\n",
|
||||
"Since the true scope of `great-ai` is the phase between proof-of-concept code and production-ready service, it is predominantly used in the [deployment notebook](/examples/simple/deploy). Feel free to skip there, or continue reading if you'd like to see the full picture.\n",
|
||||
"Since the true scope of `great-ai` is the phase between proof-of-concept code and production-ready service, it is predominantly used in the [deployment notebook](https://great-ai.scoutinscience.com/examples/simple/deploy). Feel free to skip there, or continue reading if you'd like to see the full picture.\n",
|
||||
"\n",
|
||||
"### Extract\n",
|
||||
"\n",
|
||||
|
|
@ -199,7 +199,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Next: [Part 2](/examples/simple/train)"
|
||||
"### Next: [Part 2](https://great-ai.scoutinscience.com/examples/simple/train)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -8,10 +8,10 @@
|
|||
"\n",
|
||||
"> Part 3: Create production inference function\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps implemented in this notebook.\n",
|
||||
"\n",
|
||||
"In [Part 2](/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
|
||||
"In [Part 2](https://great-ai.scoutinscience.com/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
|
||||
"\n",
|
||||
"## Create the inference function\n",
|
||||
"\n",
|
||||
|
|
|
|||
|
|
@ -6,14 +6,14 @@
|
|||
"source": [
|
||||
"# Optimise and train a model\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps implemented in this notebook.\n",
|
||||
"\n",
|
||||
"In the first part, we have cleaned and transformed our training data. We can now access this data using `great_ai.LargeFile`. Locally, it will gives us the cached version, otherwise, the latest version is downloaded from S3 or GridFS. \n",
|
||||
"\n",
|
||||
"In this part, we hyperparameter-optimise and train a simple Naive Bayes classifier which we then export for deployment using `great_ai.save_model`.\n",
|
||||
"\n",
|
||||
"## Load data that has been extracted in [part 1](/examples/simple/data)"
|
||||
"## Load data that has been extracted in [part 1](https://great-ai.scoutinscience.com/examples/simple/data)"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
@ -861,7 +861,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Next: [Part 3](/examples/simple/deploy)"
|
||||
"## Next: [Part 3](https://great-ai.scoutinscience.com/examples/simple/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -22,7 +22,7 @@ async def slow_greeter(your_name):
|
|||
await sleep(2)
|
||||
return f'Hi {your_name}!'
|
||||
```
|
||||
> Run this in development mode by executing `great-ai server.py` or `python3 -m great_ai server.py` if you're on Windows and [`great-ai` is not in your `PATH`](/how-to-guides/install).
|
||||
> Run this in development mode by executing `great-ai server.py` or `python3 -m great_ai server.py` if you're on Windows and [`great-ai` is not in your `PATH`](https://great-ai.scoutinscience.com/how-to-guides/install).
|
||||
|
||||
### Client
|
||||
|
||||
|
|
@ -48,7 +48,7 @@ print(results)
|
|||
|
||||
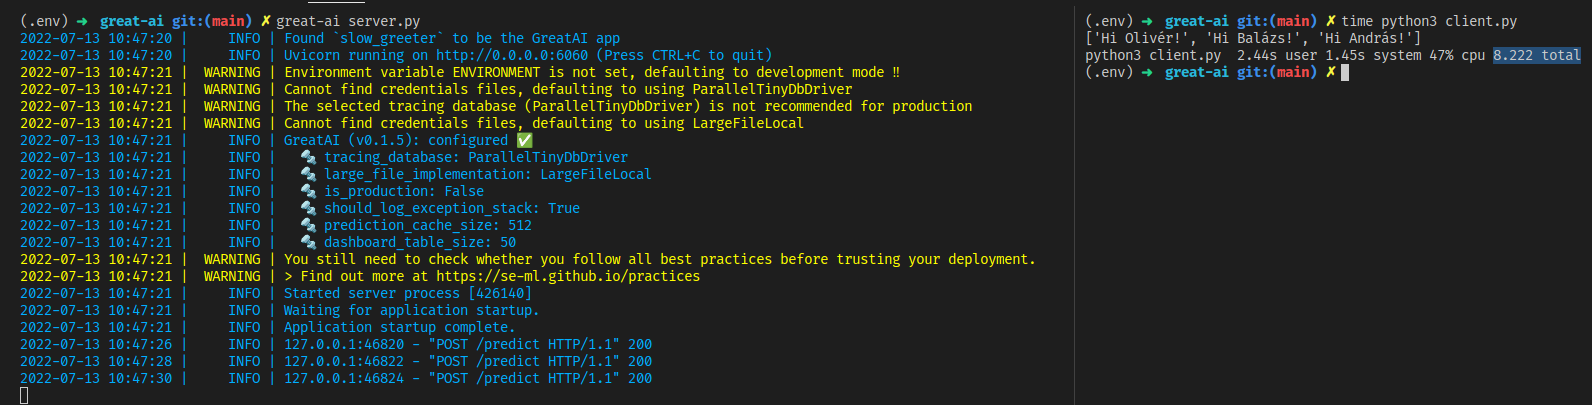
> Run this script as a regular Python script by executing `python3 client.py`.
|
||||
|
||||
{ loading=lazy }
|
||||
{ loading=lazy }
|
||||
|
||||
As you can see, everything worked as expected. There is one way to improve it, though.
|
||||
## An `async` example
|
||||
|
|
@ -86,6 +86,6 @@ asyncio.run(main())
|
|||
|
||||
> Replace `client.py` with this async client. Note that although async support is significantly more streamlined in recent Python versions, it still requires a bit more boilerplate than its synchronous counterpart.
|
||||
|
||||
{ loading=lazy }
|
||||
{ loading=lazy }
|
||||
|
||||
This also works and might be considerably quicker in some use cases.
|
||||
|
|
|
|||
|
|
@ -38,7 +38,7 @@ This not only allows you to statically type-check your code, but by default, Gre
|
|||
|
||||
## With async
|
||||
|
||||
Asynchronous code can result in immense performance gains in some instances. For example, you might rely on a third-party service, do database access, or [call a remote GreatAI instance](/how-to-guides/call-remote). In these cases, you can make your function `async` without any other changes.
|
||||
Asynchronous code can result in immense performance gains in some instances. For example, you might rely on a third-party service, do database access, or [call a remote GreatAI instance](https://great-ai.scoutinscience.com/how-to-guides/call-remote). In these cases, you can make your function `async` without any other changes.
|
||||
|
||||
```python title="async_greeter.py"
|
||||
from great_ai import GreatAI
|
||||
|
|
@ -117,4 +117,4 @@ def add_number(positive_number: int, secret: int) -> int:
|
|||
assert add_number(1).output == 5
|
||||
```
|
||||
|
||||
1. Refer to [the configuration page](/how-to-guides/configure-service) for specifying where to store your models.
|
||||
1. Refer to [the configuration page](https://great-ai.scoutinscience.com/how-to-guides/configure-service) for specifying where to store your models.
|
||||
|
|
|
|||
|
|
@ -60,7 +60,7 @@ After the initial data gathering, end-to-end feedback can also be integrated int
|
|||
|
||||
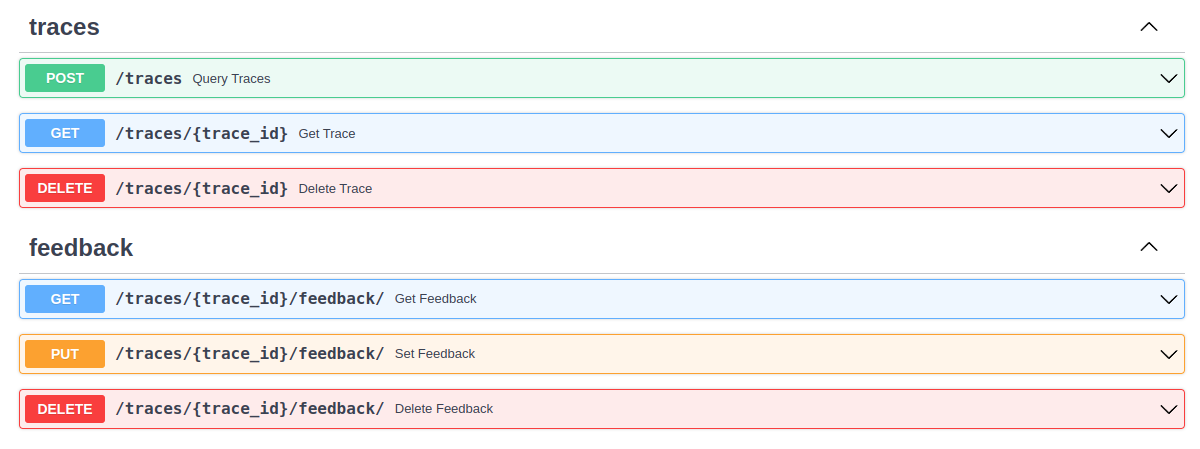
The scaffolded REST API contains endpoints for managing traces and their feedbacks.
|
||||
|
||||
{ loading=lazy }
|
||||
{ loading=lazy }
|
||||
|
||||
When [great_ai.query_ground_truth][] is executed, it implicitly filters for traces that have feedback. Therefore, both the `ground_truth` and the `online` traces that have received feedback are returned. No matter the origin of the data, it can be accessed using the same API.
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
# How to use LargeFiles
|
||||
|
||||
The functions [save_model][great_ai.use_model] and [@use_model][great_ai.use_model] wrap LargeFile instances. Hence, besides configuring [LargeFile](/reference/large-file), users have few reasons to use LargeFiles directly.
|
||||
The functions [save_model][great_ai.use_model] and [@use_model][great_ai.use_model] wrap LargeFile instances. Hence, besides configuring [LargeFile](https://great-ai.scoutinscience.com/reference/large-file), users have few reasons to use LargeFiles directly.
|
||||
|
||||
## Motivation
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
# How to perform prediction with GreatAI
|
||||
|
||||
After [creating a GreatAI service](/how-to-guides/create-service) by wrapping your prediction function, and optionally [configuring it](/how-to-guides/configure-service), it's time to do some prediction.
|
||||
After [creating a GreatAI service](https://great-ai.scoutinscience.com/how-to-guides/create-service) by wrapping your prediction function, and optionally [configuring it](https://great-ai.scoutinscience.com/how-to-guides/configure-service), it's time to do some prediction.
|
||||
|
||||
Let's take the following example:
|
||||
|
||||
|
|
|
|||
|
|
@ -110,7 +110,7 @@ However, research indicates that professionals rarely use them. This may be due
|
|||
|
||||
[:fontawesome-brands-docker: Find it on DockerHub](https://hub.docker.com/repository/docker/schmelczera/great-ai){ .md-button .md-button--primary }
|
||||
|
||||
[:fontawesome-solid-laptop-code: Check out the tutorial](/tutorial){ .md-button .md-button--primary }
|
||||
[:fontawesome-solid-laptop-code: Check out the tutorial](https://great-ai.scoutinscience.com/tutorial){ .md-button .md-button--primary }
|
||||
</div>
|
||||
|
||||
## Production use
|
||||
|
|
|
|||
|
|
@ -4,7 +4,7 @@
|
|||
from great_ai.large_file import *
|
||||
```
|
||||
|
||||
For more details about using LargeFiles, check out the [how to guide](/how-to-guides/large-file/).
|
||||
For more details about using LargeFiles, check out the [how to guide](https://great-ai.scoutinscience.com/how-to-guides/large-file/).
|
||||
|
||||
::: great_ai.large_file.LargeFileLocal
|
||||
options:
|
||||
|
|
|
|||
|
|
@ -141,11 +141,11 @@
|
|||
"\n",
|
||||
"Your service now has tracing and API scaffolding. Before deploying, replace the default local TinyDB tracing backend, configure storage and infrastructure, evaluate the model for its intended use, and review the remaining best practices. Model trustworthiness requires evidence and ongoing oversight beyond wrapping the inference function. You (or your organisation) remain responsible for deploying and operating the service.\n",
|
||||
"\n",
|
||||
"There are three main approaches to deploy a GreatAI service: For more info about them, check out [the deployment how-to](/how-to-guides/use-service).\n",
|
||||
"There are three main approaches to deploy a GreatAI service: For more info about them, check out [the deployment how-to](https://great-ai.scoutinscience.com/how-to-guides/use-service).\n",
|
||||
"\n",
|
||||
"For more thorough examples, see the [examples page](/examples/simple/data).\n",
|
||||
"For more thorough examples, see the [examples page](https://great-ai.scoutinscience.com/examples/simple/data).\n",
|
||||
"\n",
|
||||
"### [Go back to the summary](/tutorial/#summary)"
|
||||
"### [Go back to the summary](https://great-ai.scoutinscience.com/tutorial/#summary)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -4,8 +4,8 @@ Let's see `great-ai` in action by going over the lifecycle of a simple service.
|
|||
|
||||
## Objectives
|
||||
|
||||
1. You will see how the [great_ai.utilities](/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will use [great_ai.large_file](/reference/large-file) to version and store your trained model.
|
||||
1. You will see how the [great_ai.utilities](https://great-ai.scoutinscience.com/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will use [great_ai.large_file](https://great-ai.scoutinscience.com/reference/large-file) to version and store your trained model.
|
||||
3. You will use [GreatAI][great_ai.GreatAI] to add tracing and API scaffolding to your inference function, then review the remaining deployment requirements.
|
||||
|
||||
## Overview
|
||||
|
|
@ -52,7 +52,7 @@ After training and evaluating a model, it is exported using [great_ai.save_model
|
|||
save_model(model, key='my-domain-predictor')
|
||||
```
|
||||
|
||||
For more info, check out [the configuration how-to page](/how-to-guides/configure-service).
|
||||
For more info, check out [the configuration how-to page](https://great-ai.scoutinscience.com/how-to-guides/configure-service).
|
||||
|
||||
### [Deployment notebook](deploy.ipynb)
|
||||
|
||||
|
|
@ -72,10 +72,10 @@ def predict_domain(sentence, model):
|
|||
1. [@use_model][great_ai.use_model] loads and injects your model into the `predict_domain` function's `model` argument.
|
||||
You can freely reference it, knowing that the function is always provided with it.
|
||||
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. Before production, configure a suitable tracing database and storage, evaluate the model for its intended use, review the remaining best practices, and [deploy the service](/how-to-guides/use-service).
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. Before production, configure a suitable tracing database and storage, evaluate the model for its intended use, review the remaining best practices, and [deploy the service](https://great-ai.scoutinscience.com/how-to-guides/use-service).
|
||||
|
||||
<div style="display: flex; justify-content: space-evenly;" markdown>
|
||||
[:material-book: Learn about all the features](/how-to-guides/create-service){ .md-button .md-button--primary }
|
||||
[:material-book: Learn about all the features](https://great-ai.scoutinscience.com/how-to-guides/create-service){ .md-button .md-button--primary }
|
||||
|
||||
[:material-test-tube: Look at more examples](/examples/simple/data){ .md-button .md-button--secondary }
|
||||
[:material-test-tube: Look at more examples](https://great-ai.scoutinscience.com/examples/simple/data){ .md-button .md-button--secondary }
|
||||
</div>
|
||||
|
|
|
|||
|
|
@ -32,7 +32,7 @@
|
|||
"source": [
|
||||
"First, we have to get some data. After downloading it [from here](https://github.com/allenai/scibert/tree/master/data/text_classification/mag), we might notice that the dataset is in [JSON Lines](https://jsonlines.org/) format (each line is a separate JSON document). \n",
|
||||
"\n",
|
||||
"Let's write a function which takes a single line and returns the sentence and the corresponding label from it. Before returning, the sentence is also [cleaned](/reference/utilities/#great_ai.utilities.clean.clean) to remove any LaTeX, XML, unicode, PDF-extraction artifacts."
|
||||
"Let's write a function which takes a single line and returns the sentence and the corresponding label from it. Before returning, the sentence is also [cleaned](https://great-ai.scoutinscience.com/reference/utilities/#great_ai.utilities.clean.clean) to remove any LaTeX, XML, unicode, PDF-extraction artifacts."
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
@ -58,7 +58,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Now, we can load the dataset and extract the *training* samples from it. Since we're impatient, we can do it in parallel using the [`simple_parallel_map`](/reference/utilities/#great_ai.utilities.simple_parallel_map) function.\n",
|
||||
"Now, we can load the dataset and extract the *training* samples from it. Since we're impatient, we can do it in parallel using the [`simple_parallel_map`](https://great-ai.scoutinscience.com/reference/utilities/#great_ai.utilities.simple_parallel_map) function.\n",
|
||||
"\n",
|
||||
"> Open files in Python are iterable: in text mode, each iteration returns the next line."
|
||||
]
|
||||
|
|
@ -292,7 +292,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### [Let's continue by finishing the deployment in the next notebook.](/tutorial/deploy)"
|
||||
"### [Let's continue by finishing the deployment in the next notebook.](https://great-ai.scoutinscience.com/tutorial/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
Loading…
Reference in a new issue