Make documentation links usable from repository previews
This commit is contained in:

parent
34368bbe50
commit
e446d95855
7 changed files with 39 additions and 39 deletions
|
|
@ -6,7 +6,7 @@
|
|||
"source": [
|
||||
"# Explore data and feasibility of approach\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
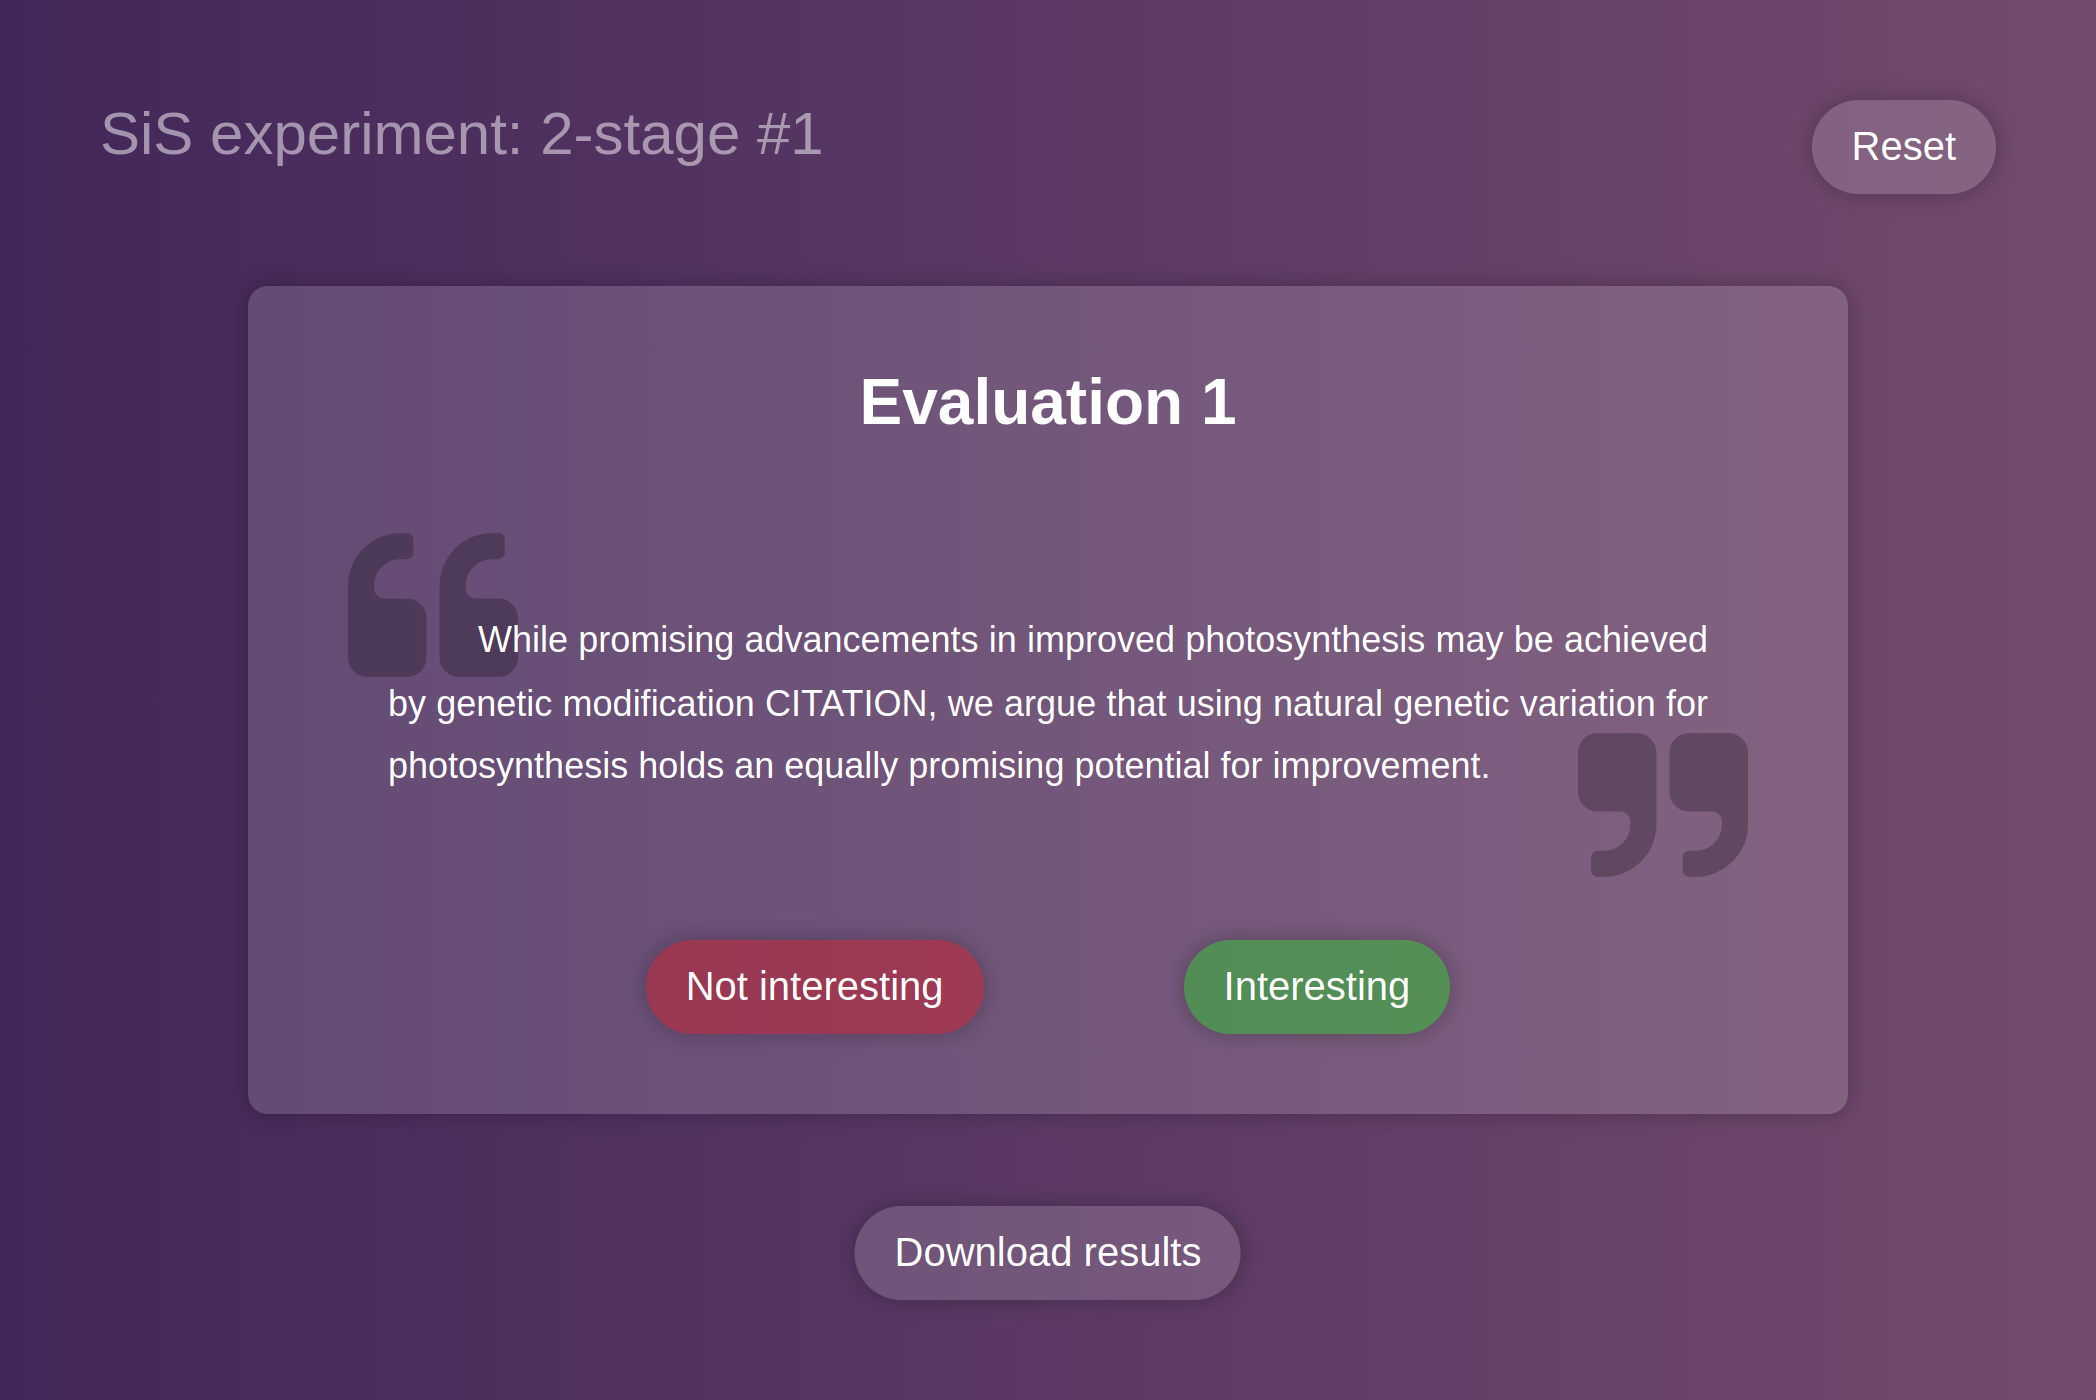
"We had asked our clients and in-house experts to annotate sentences using a rigorous guideline. The aim is to decide on which sentences they would like to see in a summary for a paper.\n",
|
||||
"\n",
|
||||
|
|
@ -276,7 +276,7 @@
|
|||
"source": [
|
||||
"We get an F1-score of 0.78 without any hyperparameter-optimisation; this task may be feasible to solve with AI.\n",
|
||||
"\n",
|
||||
"Next: [Part 2](/examples/scibert/train)"
|
||||
"Next: [Part 2](https://great-ai.scoutinscience.com/examples/scibert/train)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -290,7 +290,7 @@
|
|||
"metadata": {},
|
||||
"source": [
|
||||
"In this case, the service is built as a docker image, pushed to our image registry and subsequent rolling update is performed in the production cluster.\n",
|
||||
"To check out the Dockerimage, go to [the additional files page](/examples/scibert/additional-files)."
|
||||
"To check out the Dockerimage, go to [the additional files page](https://great-ai.scoutinscience.com/examples/scibert/additional-files)."
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -7,8 +7,8 @@ This is a simplified example illustrating how `great-ai` is used in practice at
|
|||
|
||||
## Objectives
|
||||
|
||||
1. You will see how the [great_ai.utilities](/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will see how [great_ai.large_file](/reference/large-file) can be used to version and store your trained model.
|
||||
1. You will see how the [great_ai.utilities](https://great-ai.scoutinscience.com/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will see how [great_ai.large_file](https://great-ai.scoutinscience.com/reference/large-file) can be used to version and store your trained model.
|
||||
3. You will see how [GreatAI][great_ai.GreatAI] should be used to prepare your model for a robust and responsible deployment.
|
||||
4. You will see multiple ways of customising your deployment.
|
||||
|
||||
|
|
@ -37,13 +37,13 @@ We load and analyse the data by calculating inter-rater reliability and checking
|
|||
|
||||
We simply fine-tune SciBERT.
|
||||
|
||||
After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](/how-to-guides/configure-service).
|
||||
After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](https://great-ai.scoutinscience.com/how-to-guides/configure-service).
|
||||
|
||||
### [Deployment notebook](deploy.ipynb)
|
||||
|
||||
We customise the GreatAI configuration, create custom caching for the model and implement an inference function that can be hardened by wrapping it in a [GreatAI][great_ai.GreatAI] instance. We also extract the attention weights as a quasi-explanation.
|
||||
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](/how-to-guides/use-service)
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](https://great-ai.scoutinscience.com/how-to-guides/use-service)
|
||||
|
||||
#### [Additional files](additional-files.md)
|
||||
|
||||
|
|
|
|||
|
|
@ -341,7 +341,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Next: [Part 3](/examples/scibert/deploy)"
|
||||
"Next: [Part 3](https://great-ai.scoutinscience.com/examples/scibert/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -8,10 +8,10 @@
|
|||
"\n",
|
||||
"Here, we solve a problem similar to the tutorial's but with an explainable Naive Bayes classifier and more best practices. In short, we train a domain classifier on the [semantic scholar dataset](https://api.semanticscholar.org/corpus) by taking full advantage of `great-ai`. Subsequently, we create a production-ready deployment.\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps of a typical AI-development lifecycle implemented in this notebook.\n",
|
||||
"\n",
|
||||
"Since the true scope of `great-ai` is the phase between proof-of-concept code and production-ready service, it is predominantly used in the [deployment notebook](/examples/simple/deploy). Feel free to skip there, or continue reading if you'd like to see the full picture.\n",
|
||||
"Since the true scope of `great-ai` is the phase between proof-of-concept code and production-ready service, it is predominantly used in the [deployment notebook](https://great-ai.scoutinscience.com/examples/simple/deploy). Feel free to skip there, or continue reading if you'd like to see the full picture.\n",
|
||||
"\n",
|
||||
"### Extract\n",
|
||||
"\n",
|
||||
|
|
@ -199,7 +199,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Next: [Part 2](/examples/simple/train)"
|
||||
"### Next: [Part 2](https://great-ai.scoutinscience.com/examples/simple/train)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -8,10 +8,10 @@
|
|||
"\n",
|
||||
"> Part 3: Create production inference function\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps implemented in this notebook.\n",
|
||||
"\n",
|
||||
"In [Part 2](/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
|
||||
"In [Part 2](https://great-ai.scoutinscience.com/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
|
||||
"\n",
|
||||
"## Create the inference function\n",
|
||||
"\n",
|
||||
|
|
|
|||
|
|
@ -6,14 +6,14 @@
|
|||
"source": [
|
||||
"# Optimise and train a model\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps implemented in this notebook.\n",
|
||||
"\n",
|
||||
"In the first part, we have cleaned and transformed our training data. We can now access this data using `great_ai.LargeFile`. Locally, it will gives us the cached version, otherwise, the latest version is downloaded from S3 or GridFS. \n",
|
||||
"\n",
|
||||
"In this part, we hyperparameter-optimise and train a simple Naive Bayes classifier which we then export for deployment using `great_ai.save_model`.\n",
|
||||
"\n",
|
||||
"## Load data that has been extracted in [part 1](/examples/simple/data)"
|
||||
"## Load data that has been extracted in [part 1](https://great-ai.scoutinscience.com/examples/simple/data)"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
@ -861,7 +861,7 @@
|
|||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Next: [Part 3](/examples/simple/deploy)"
|
||||
"## Next: [Part 3](https://great-ai.scoutinscience.com/examples/simple/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
Loading…
Reference in a new issue