Publish docs
This commit is contained in:

parent
7c049388f6
commit
77016417f2
25 changed files with 65 additions and 58 deletions
|
|
@ -1,4 +1,4 @@
|
|||
name: Publish documentation
|
||||
name: Publish documentation to great-ai.schmelczer.dev
|
||||
|
||||
on:
|
||||
push:
|
||||
|
|
@ -9,10 +9,18 @@ on:
|
|||
- 'mkdocs.yaml'
|
||||
- 'pyproject.toml'
|
||||
- '.forgejo/workflows/docs.yml'
|
||||
pull_request:
|
||||
branches: [main]
|
||||
paths:
|
||||
- 'docs/**'
|
||||
- 'great_ai/**'
|
||||
- 'mkdocs.yaml'
|
||||
- 'pyproject.toml'
|
||||
- '.forgejo/workflows/docs.yml'
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: pages
|
||||
group: docs-${{ github.ref }}
|
||||
cancel-in-progress: false
|
||||
|
||||
jobs:
|
||||
|
|
@ -42,11 +50,10 @@ jobs:
|
|||
. .venv/bin/activate
|
||||
mkdocs build
|
||||
|
||||
# The old workflow ran `mkdocs gh-deploy` (GitHub Pages); on this instance
|
||||
# built sites are rsynced into the host /pages mount that nginx serves,
|
||||
# via the shared ci-actions/deploy-pages action — same as photos/reconcile.
|
||||
- name: Deploy to pages mount
|
||||
if: github.ref == 'refs/heads/main'
|
||||
# As in reconcile, publish through the shared action to /pages/great-ai,
|
||||
# served at https://great-ai.schmelczer.dev.
|
||||
- name: Deploy to great-ai.schmelczer.dev
|
||||
if: (github.event_name == 'push' || github.event_name == 'workflow_dispatch') && github.ref == 'refs/heads/main'
|
||||
uses: http://forgejo:3000/andras/ci-actions/deploy-pages@main
|
||||
with:
|
||||
source: site
|
||||
|
|
|
|||
|
|
@ -36,7 +36,7 @@ from great_ai import GreatAI
|
|||
\
|
||||
@GreatAI.create
|
||||
def hello_world(name: str) -> str:
|
||||
"""Learn more about GreatAI at https://great-ai.scoutinscience.com"""
|
||||
"""Learn more about GreatAI at https://great-ai.schmelczer.dev"""
|
||||
return f"Hello {name}!"
|
||||
EOF
|
||||
|
||||
|
|
|
|||
|
|
@ -39,7 +39,7 @@ That's it. Your GreatAI service is _nearly_ ready for production use. Many of th
|
|||
|
||||
Before production, replace the default local TinyDB tracing database with a production-suitable backend, configure storage and deployment infrastructure, and review the remaining best practices for your use case.
|
||||
|
||||
> **Published documentation:** [Read the rendered guides, API reference, and notebooks](https://great-ai.scoutinscience.com). The files under `docs/` use MkDocs features that repository previews may not render.
|
||||
> **Published documentation:** [Read the rendered guides, API reference, and notebooks](https://great-ai.schmelczer.dev). The files under `docs/` use MkDocs features that repository previews may not render.
|
||||
|
||||
## Why is this GREAT?
|
||||
|
||||
|
|
@ -57,11 +57,11 @@ GreatAI fits between the prototype and deployment phases of your AI development
|
|||
|
||||
There are other existing solutions aiming to facilitate this phase. [Amazon SageMaker](https://aws.amazon.com/sagemaker) and [Seldon Core](https://docs.seldon.ai/seldon-core-2) provide the most comprehensive suite of features. If you have the opportunity to use them, do that because they're great.
|
||||
|
||||
However, [research indicates](https://great-ai.scoutinscience.com) that professionals rarely use them. This may be due to their inherent setup and operational complexity. **GreatAI is designed to be as simple to use as possible.** Its straightforward, high-level API and sensible default configuration make it easy to start using. Despite its relative simplicity over Seldon Core, it still implements many of the [SE4ML best practices](https://se-ml.github.io), and thus, can meaningfully improve your deployment without requiring prohibitively great effort.
|
||||
However, [research indicates](https://great-ai.schmelczer.dev) that professionals rarely use them. This may be due to their inherent setup and operational complexity. **GreatAI is designed to be as simple to use as possible.** Its straightforward, high-level API and sensible default configuration make it easy to start using. Despite its relative simplicity over Seldon Core, it still implements many of the [SE4ML best practices](https://se-ml.github.io), and thus, can meaningfully improve your deployment without requiring prohibitively great effort.
|
||||
|
||||
## [Learn more](https://great-ai.scoutinscience.com)
|
||||
## [Learn more](https://great-ai.schmelczer.dev)
|
||||
|
||||
[Check out the full documentation here](https://great-ai.scoutinscience.com).
|
||||
[Check out the full documentation here](https://great-ai.schmelczer.dev).
|
||||
|
||||
## Find `great-ai` on [PyPI](https://pypi.org/project/great-ai/)
|
||||
|
||||
|
|
|
|||
|
|
@ -1 +0,0 @@
|
|||
great-ai.scoutinscience.com
|
||||
|
|
@ -272,7 +272,7 @@
|
|||
"metadata": {},
|
||||
"source": [
|
||||
"In this case, the service is built as a docker image, pushed to our image registry and subsequent rolling update is performed in the production cluster.\n",
|
||||
"To check out the Dockerimage, go to [the additional files page](https://great-ai.scoutinscience.com/examples/scibert/additional-files)."
|
||||
"To check out the Dockerimage, go to [the additional files page](https://great-ai.schmelczer.dev/examples/scibert/additional-files)."
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -7,8 +7,8 @@ This is a simplified example illustrating how `great-ai` is used in practice at
|
|||
|
||||
## Objectives
|
||||
|
||||
1. You will see how the [great_ai.utilities](https://great-ai.scoutinscience.com/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will see how [great_ai.large_file](https://great-ai.scoutinscience.com/reference/large-file) can be used to version and store your trained model.
|
||||
1. You will see how the [great_ai.utilities](https://great-ai.schmelczer.dev/reference/utilities) can integrate into your Data Science workflow.
|
||||
2. You will see how [great_ai.large_file](https://great-ai.schmelczer.dev/reference/large-file) can be used to version and store your trained model.
|
||||
3. You will see how [GreatAI][great_ai.GreatAI] should be used to prepare your model for a robust and responsible deployment.
|
||||
4. You will see multiple ways of customising your deployment.
|
||||
|
||||
|
|
@ -37,13 +37,13 @@ We load and analyse the data by calculating inter-rater reliability and checking
|
|||
|
||||
We simply fine-tune SciBERT.
|
||||
|
||||
After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](https://great-ai.scoutinscience.com/how-to-guides/configure-service).
|
||||
After training and evaluating a model, it is exported using [great_ai.save_model][]. For more info, check out [the configuration how-to page](https://great-ai.schmelczer.dev/how-to-guides/configure-service).
|
||||
|
||||
### [Deployment notebook](deploy.ipynb)
|
||||
|
||||
We customise the GreatAI configuration, create custom caching for the model and implement an inference function that can be hardened by wrapping it in a [GreatAI][great_ai.GreatAI] instance. We also extract the attention weights as a quasi-explanation.
|
||||
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](https://great-ai.scoutinscience.com/how-to-guides/use-service)
|
||||
Finally, we test the model's inference function through the GreatAI dashboard. [The only thing left is to deploy the hardened service properly.](https://great-ai.schmelczer.dev/how-to-guides/use-service)
|
||||
|
||||
#### [Additional files](additional-files.md)
|
||||
|
||||
|
|
|
|||
|
|
@ -348,7 +348,7 @@
|
|||
"id": "cell-8",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"The [saved historical run](https://great-ai.scoutinscience.com/examples/scibert/validation-results.json) selected a checkpoint with **validation binary F1 of 0.8966** (recorded value: 0.896551724137931). This validation split was also used for early stopping and checkpoint selection, so the number is not an independent test result or macro F1. The historical split seed was not recorded; the seeded code above defines future runs and does not reproduce that split. Its results are saved to `models/validation_results.json` and `models/validation-run.json`.\n",
|
||||
"The [saved historical run](https://great-ai.schmelczer.dev/examples/scibert/validation-results.json) selected a checkpoint with **validation binary F1 of 0.8966** (recorded value: 0.896551724137931). This validation split was also used for early stopping and checkpoint selection, so the number is not an independent test result or macro F1. The historical split seed was not recorded; the seeded code above defines future runs and does not reproduce that split. Its results are saved to `models/validation_results.json` and `models/validation-run.json`.\n",
|
||||
"\n",
|
||||
"To estimate performance after model selection, evaluate once on a separate untouched test split. We make no test-set performance claim here. Next, store the selected model for deployment."
|
||||
]
|
||||
|
|
@ -409,7 +409,7 @@
|
|||
"id": "cell-10",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Next: [Part 3](https://great-ai.scoutinscience.com/examples/scibert/deploy)"
|
||||
"Next: [Part 3](https://great-ai.schmelczer.dev/examples/scibert/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -185,7 +185,7 @@
|
|||
"id": "cell-10",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Next: [Part 2](https://great-ai.scoutinscience.com/examples/simple/train)"
|
||||
"### Next: [Part 2](https://great-ai.schmelczer.dev/examples/simple/train)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -9,10 +9,10 @@
|
|||
"\n",
|
||||
"> Part 3: Create production inference function\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps implemented in this notebook.\n",
|
||||
"\n",
|
||||
"In [Part 2](https://great-ai.scoutinscience.com/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
|
||||
"In [Part 2](https://great-ai.schmelczer.dev/examples/simple/train), we trained our AI model. Now, it's time to create **G**eneral **R**obust **E**nd-to-end **A**utomated **T**rustworthy deployment.\n",
|
||||
"\n",
|
||||
"## Create the inference function\n",
|
||||
"\n",
|
||||
|
|
|
|||
|
|
@ -7,14 +7,14 @@
|
|||
"source": [
|
||||
"# Optimise and train a model\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"> The blue boxes show the steps implemented in this notebook.\n",
|
||||
"\n",
|
||||
"Run `data.ipynb` first. We read its ground truth from the shared local TinyDB database. The default uses a compact parameter search suitable for the bundled sample; `GREAT_AI_NOTEBOOK_FULL=1` enables the original larger search on the full MAG training data. \n",
|
||||
"\n",
|
||||
"In this part, we hyperparameter-optimise and train a simple Naive Bayes classifier which we then export for deployment using `great_ai.save_model`.\n",
|
||||
"\n",
|
||||
"## Load data that has been extracted in [part 1](https://great-ai.scoutinscience.com/examples/simple/data)"
|
||||
"## Load data that has been extracted in [part 1](https://great-ai.schmelczer.dev/examples/simple/data)"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
@ -138,7 +138,7 @@
|
|||
"\n",
|
||||
"Each paper may have several accepted labels. We expand it into one training row per label for this single-label classifier, but keep all rows with the same paper text in one cross-validation fold using `GroupKFold`. The final train/test split was already made by paper in Part 1, before expansion.\n",
|
||||
"\n",
|
||||
"The search uses macro F1 on the expanded single-label validation rows as a training surrogate. This differs from the top-1 hit rate and fixed-target multilabel metrics used to evaluate the deployed label sets in [Part 3](https://great-ai.scoutinscience.com/examples/simple/deploy). Rerun the search to obtain results for these grouped folds; the previous ungrouped outputs have been removed."
|
||||
"The search uses macro F1 on the expanded single-label validation rows as a training surrogate. This differs from the top-1 hit rate and fixed-target multilabel metrics used to evaluate the deployed label sets in [Part 3](https://great-ai.schmelczer.dev/examples/simple/deploy). Rerun the search to obtain results for these grouped folds; the previous ungrouped outputs have been removed."
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
@ -2783,7 +2783,7 @@
|
|||
"id": "cell-11",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Next: [Part 3](https://great-ai.scoutinscience.com/examples/simple/deploy)"
|
||||
"## Next: [Part 3](https://great-ai.schmelczer.dev/examples/simple/deploy)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
|
|||
|
|
@ -22,7 +22,7 @@ async def slow_greeter(your_name):
|
|||
await sleep(2)
|
||||
return f'Hi {your_name}!'
|
||||
```
|
||||
> Run this in development mode by executing `great-ai server.py` or `python3 -m great_ai server.py` if you're on Windows and [`great-ai` is not in your `PATH`](https://great-ai.scoutinscience.com/how-to-guides/install).
|
||||
> Run this in development mode by executing `great-ai server.py` or `python3 -m great_ai server.py` if you're on Windows and [`great-ai` is not in your `PATH`](https://great-ai.schmelczer.dev/how-to-guides/install).
|
||||
|
||||
### Client
|
||||
|
||||
|
|
@ -48,7 +48,7 @@ print(results)
|
|||
|
||||
> Run this script as a regular Python script by executing `python3 client.py`.
|
||||
|
||||
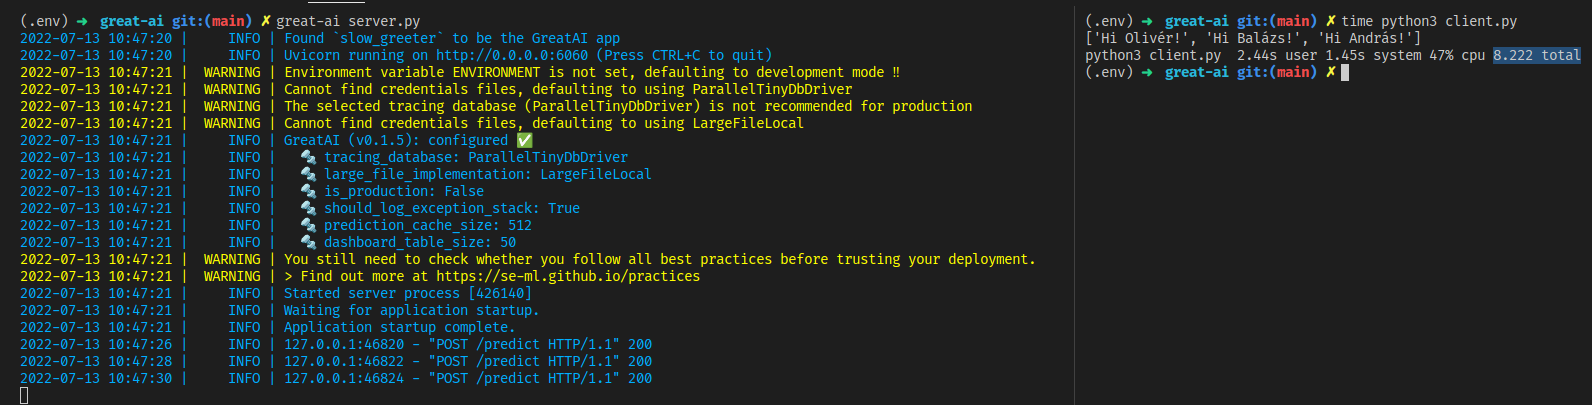{ loading=lazy }
|
||||
{ loading=lazy }
|
||||
|
||||
As you can see, everything worked as expected. There is one way to improve it, though.
|
||||
## An `async` example
|
||||
|
|
@ -86,6 +86,6 @@ asyncio.run(main())
|
|||
|
||||
> Replace `client.py` with this async client. Note that although async support is significantly more streamlined in recent Python versions, it still requires a bit more boilerplate than its synchronous counterpart.
|
||||
|
||||
{ loading=lazy }
|
||||
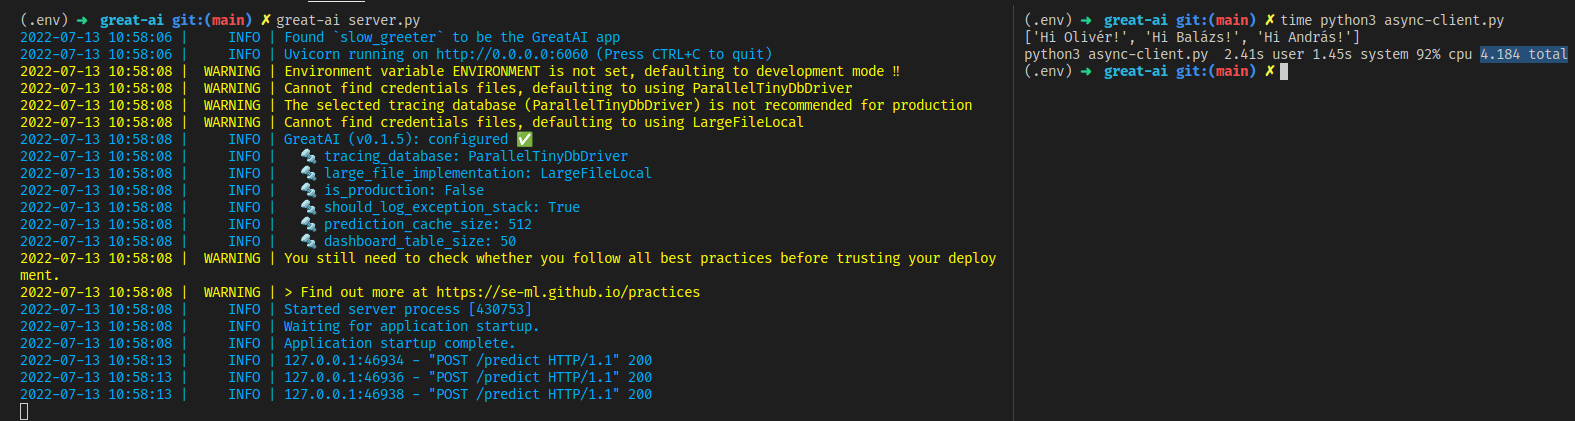{ loading=lazy }
|
||||
|
||||
This also works and might be considerably quicker in some use cases.
|
||||
|
|
|
|||
|
|
@ -38,7 +38,7 @@ This not only allows you to statically type-check your code, but by default, Gre
|
|||
|
||||
## With async
|
||||
|
||||
Asynchronous code can result in immense performance gains in some instances. For example, you might rely on a third-party service, do database access, or [call a remote GreatAI instance](https://great-ai.scoutinscience.com/how-to-guides/call-remote). In these cases, you can make your function `async` without any other changes.
|
||||
Asynchronous code can result in immense performance gains in some instances. For example, you might rely on a third-party service, do database access, or [call a remote GreatAI instance](https://great-ai.schmelczer.dev/how-to-guides/call-remote). In these cases, you can make your function `async` without any other changes.
|
||||
|
||||
```python title="async_greeter.py"
|
||||
from great_ai import GreatAI
|
||||
|
|
@ -117,4 +117,4 @@ def add_number(positive_number: int, secret: int) -> int:
|
|||
assert add_number(1).output == 5
|
||||
```
|
||||
|
||||
1. Refer to [the configuration page](https://great-ai.scoutinscience.com/how-to-guides/configure-service) for specifying where to store your models.
|
||||
1. Refer to [the configuration page](https://great-ai.schmelczer.dev/how-to-guides/configure-service) for specifying where to store your models.
|
||||
|
|
|
|||
|
|
@ -60,7 +60,7 @@ After the initial data gathering, end-to-end feedback can also be integrated int
|
|||
|
||||
The scaffolded REST API contains endpoints for managing traces and their feedbacks.
|
||||
|
||||
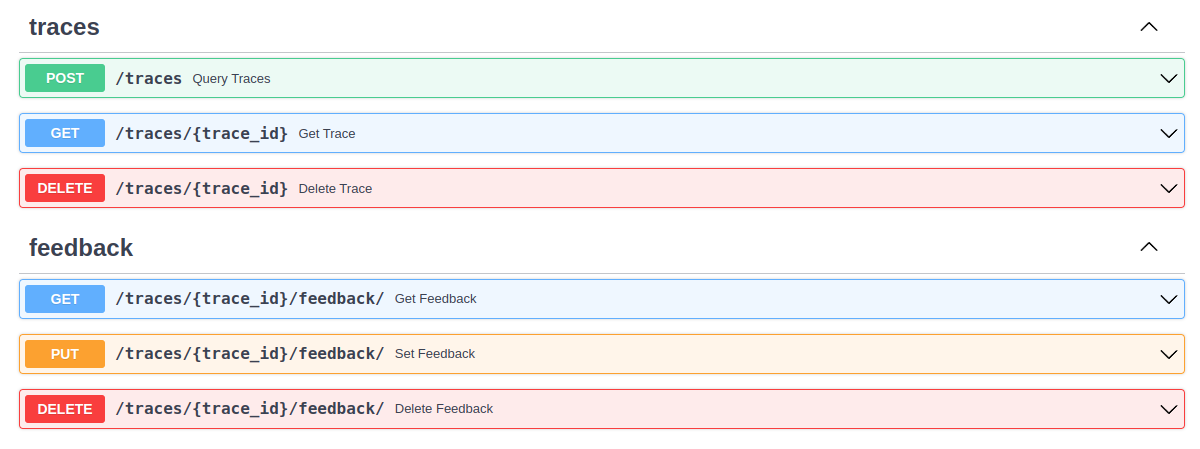{ loading=lazy }
|
||||
{ loading=lazy }
|
||||
|
||||
When [great_ai.query_ground_truth][] is executed, it implicitly filters for traces that have feedback. Therefore, both the `ground_truth` and the `online` traces that have received feedback are returned. No matter the origin of the data, it can be accessed using the same API.
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
# How to use LargeFiles
|
||||
|
||||
The functions [save_model][great_ai.use_model] and [@use_model][great_ai.use_model] wrap LargeFile instances. Hence, besides configuring [LargeFile](https://great-ai.scoutinscience.com/reference/large-file), users have few reasons to use LargeFiles directly.
|
||||
The functions [save_model][great_ai.use_model] and [@use_model][great_ai.use_model] wrap LargeFile instances. Hence, besides configuring [LargeFile](https://great-ai.schmelczer.dev/reference/large-file), users have few reasons to use LargeFiles directly.
|
||||
|
||||
## Motivation
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
# How to perform prediction with GreatAI
|
||||
|
||||
After [creating a GreatAI service](https://great-ai.scoutinscience.com/how-to-guides/create-service) by wrapping your prediction function, and optionally [configuring it](https://great-ai.scoutinscience.com/how-to-guides/configure-service), it's time to do some prediction.
|
||||
After [creating a GreatAI service](https://great-ai.schmelczer.dev/how-to-guides/create-service) by wrapping your prediction function, and optionally [configuring it](https://great-ai.schmelczer.dev/how-to-guides/configure-service), it's time to do some prediction.
|
||||
|
||||
Let's take the following example:
|
||||
|
||||
|
|
@ -107,7 +107,7 @@ COPY . .
|
|||
CMD ["deploy.ipynb"]
|
||||
```
|
||||
|
||||
Create an `s3.ini` with the S3 keys described in the [configuration guide](https://great-ai.scoutinscience.com/how-to-guides/configure-service/#s3-compatible). Use concrete values in this build configuration: `ENV:` references are resolved inside the build container, which does not inherit your shell's environment. Replace `my-domain-predictor` with the key used when saving your model.
|
||||
Create an `s3.ini` with the S3 keys described in the [configuration guide](https://great-ai.schmelczer.dev/how-to-guides/configure-service/#s3-compatible). Use concrete values in this build configuration: `ENV:` references are resolved inside the build container, which does not inherit your shell's environment. Replace `my-domain-predictor` with the key used when saving your model.
|
||||
|
||||
Keep credentials and any local model cache out of `COPY . .` by adding these entries to your project's `.dockerignore`:
|
||||
|
||||
|
|
|
|||
|
|
@ -88,7 +88,7 @@ great-ai demo.py
|
|||
!!! success
|
||||
Your GreatAI service is _nearly_ ready for production use. Many of the [SE4ML best practices](https://se-ml.github.io){ target=_blank } are configured and implemented automatically.
|
||||
|
||||
Before production, replace the default local TinyDB tracing database with a production-suitable backend, [configure storage](https://great-ai.scoutinscience.com/how-to-guides/configure-service/) and [deployment infrastructure](https://great-ai.scoutinscience.com/how-to-guides/use-service/), and review the remaining best practices for your use case. Wrapping a function provides tracing and API scaffolding; model trustworthiness still requires use-case-specific evaluation and ongoing oversight.
|
||||
Before production, replace the default local TinyDB tracing database with a production-suitable backend, [configure storage](https://great-ai.schmelczer.dev/how-to-guides/configure-service/) and [deployment infrastructure](https://great-ai.schmelczer.dev/how-to-guides/use-service/), and review the remaining best practices for your use case. Wrapping a function provides tracing and API scaffolding; model trustworthiness still requires use-case-specific evaluation and ongoing oversight.
|
||||
|
||||
## Why is this GREAT?
|
||||
|
||||
|
|
@ -114,7 +114,7 @@ However, research indicates that professionals rarely use them. This may be due
|
|||
|
||||
[:fontawesome-brands-docker: Find it on DockerHub](https://hub.docker.com/repository/docker/schmelczera/great-ai){ .md-button .md-button--primary }
|
||||
|
||||
[:fontawesome-solid-laptop-code: Check out the tutorial](https://great-ai.scoutinscience.com/tutorial){ .md-button .md-button--primary }
|
||||
[:fontawesome-solid-laptop-code: Check out the tutorial](https://great-ai.schmelczer.dev/tutorial){ .md-button .md-button--primary }
|
||||
</div>
|
||||
|
||||
## Production use
|
||||
|
|
|
|||
|
|
@ -6,7 +6,7 @@
|
|||
<meta property="og:url" content="">
|
||||
<meta property="og:description" content="Transform your prototype AI code into production-ready software.">
|
||||
<meta property="og:type" content="">
|
||||
<meta property="og:image" content=https://great-ai.scoutinscience.com/media/og-image.png>
|
||||
<meta property="og:image" content=https://great-ai.schmelczer.dev/media/og-image.png>
|
||||
|
||||
<style>
|
||||
.jupyter-wrapper a {
|
||||
|
|
|
|||
|
|
@ -4,7 +4,7 @@
|
|||
from great_ai.large_file import *
|
||||
```
|
||||
|
||||
For more details about using LargeFiles, check out the [how to guide](https://great-ai.scoutinscience.com/how-to-guides/large-file/).
|
||||
For more details about using LargeFiles, check out the [how to guide](https://great-ai.schmelczer.dev/how-to-guides/large-file/).
|
||||
|
||||
::: great_ai.large_file.LargeFileLocal
|
||||
options:
|
||||
|
|
|
|||
|
|
@ -50,7 +50,7 @@ MAG needs no further preprocessing if we aim to match SciBERT's setup \cite{belt
|
|||
|
||||
Our aims are twofold: (1) to evaluate a sentence classification model on MAG and compare it with the prior art; and (2) to retrain and apply this model for classifying publication metadata (including abstracts). This would allow the ScoutinScience Platform to select an appropriate processing pipeline which has been trained on a matching vocabulary (and domain) for each publication.
|
||||
|
||||
It seems reasonable that only considering the distribution (frequencies) of individual terms may be sufficient. For testing this hypothesis, a unigram language model --- Multinomial Naïve Bayes (MNB) --- is constructed, and its accuracy is compared with SciBERT's. The former definitely aligns with the advice to \textit{Use The Most Efficient Models}. Using the MNB implementation of scikit-learn \cite{pedregosa2011scikit}, it only took 71 lines of code to create, hyperparameter optimise, and test a text classifier.\footnote{The code is available at \href{https://great-ai.scoutinscience.com/tutorial/}{great-ai.scoutinscience.com/tutorial}.} This further proves how simple it is to use standard packages. The code can be considered for satisfying the \textit{Automate Hyper-Parameter Optimisation} best practice since it also implements an automated hyperparameter sweep.
|
||||
It seems reasonable that only considering the distribution (frequencies) of individual terms may be sufficient. For testing this hypothesis, a unigram language model --- Multinomial Naïve Bayes (MNB) --- is constructed, and its accuracy is compared with SciBERT's. The former definitely aligns with the advice to \textit{Use The Most Efficient Models}. Using the MNB implementation of scikit-learn \cite{pedregosa2011scikit}, it only took 71 lines of code to create, hyperparameter optimise, and test a text classifier.\footnote{The code is available at \href{https://great-ai.schmelczer.dev/tutorial/}{great-ai.schmelczer.dev/tutorial}.} This further proves how simple it is to use standard packages. The code can be considered for satisfying the \textit{Automate Hyper-Parameter Optimisation} best practice since it also implements an automated hyperparameter sweep.
|
||||
|
||||
The sentences are tokenised into words and vectorised with TF-IDF (with logarithmic term frequency) \cite{buckley1985implementation}, the hyperparameters found via 10-fold cross-validation on the \textit{train} split lead to filtering out tokens which occur in fewer than five documents or more than 5\% of the documents.
|
||||
|
||||
|
|
@ -80,7 +80,7 @@ When this model is applied to the \textit{test} split of MAG, we get the confusi
|
|||
|
||||
It is, of course, not entirely surprising that the sophisticated transformer architecture of SciBERT is not necessary for a straightforward task like this. Apart from phrases, the relations between separate words of a sentence do not carry nearly as much discriminative power as the identity of the terms \cite{hand2001idiot}; hence, there is little reason for using an attention mechanism. The fact that SciBERT even works in any way on this task is already a testament to its general applicability. Nevertheless, this short experiment has proved that we can safely opt for using MNB for production.
|
||||
|
||||
Since Multinomial Naïve Bayes is best at returning a single label and SSC has multiple labels per datapoint: for evaluation purposes, it is checked whether the returned label is contained in the labels of the ground truth. On this dataset, MNB achieves a lower macro-average than on MAG, with an F1-score of 0.59.\footnote{The code for this is available at \href{https://great-ai.scoutinscience.com/examples/simple/deploy}{great-ai.scoutinscience.com/examples/simple/deploy}.} The weighted-average F1 is 0.70, and the overall accuracy is also 70\%. The substantial difference between the macro and weighted averages comes from the unbalanced distribution of the labels. The lower F1-score is not surprising because this dataset has more than twice as many classes. Additionally, the mistakes made are defensible when we look at Figure \ref{fig:ss-confusion}: most of them are between related domains.
|
||||
Since Multinomial Naïve Bayes is best at returning a single label and SSC has multiple labels per datapoint: for evaluation purposes, it is checked whether the returned label is contained in the labels of the ground truth. On this dataset, MNB achieves a lower macro-average than on MAG, with an F1-score of 0.59.\footnote{The code for this is available at \href{https://great-ai.schmelczer.dev/examples/simple/deploy}{great-ai.schmelczer.dev/examples/simple/deploy}.} The weighted-average F1 is 0.70, and the overall accuracy is also 70\%. The substantial difference between the macro and weighted averages comes from the unbalanced distribution of the labels. The lower F1-score is not surprising because this dataset has more than twice as many classes. Additionally, the mistakes made are defensible when we look at Figure \ref{fig:ss-confusion}: most of them are between related domains.
|
||||
|
||||
\begin{displayquote}
|
||||
This is the usual point where papers conclude: a proof-of-concept/prototype has been built, and its performance demonstrated, measured --- and usually --- explained. Nonetheless, in an industrial setting, our problem is far from being solved: it has yet to be deployed.
|
||||
|
|
@ -186,7 +186,7 @@ assert add_number(12).output == 417
|
|||
|
||||
Coincidentally, deployment best practices can be easily implemented in this wrapper layer. In the first iteration, these are input validation, persisting traces, online monitoring, and generating documentation. Input validation may be used to \textit{Check that Input Data is Complete, Balanced and Well Distributed}. Traces are essential for both \textit{Log Production Predictions with the Model's Version and Input Data} and \textit{Provide Audit Trails}. However, traces can also indirectly help \textbf{Robustness} because even production systems cannot be expected to be perfect. Saving and letting the users filter on encountered errors while allowing them to correlate those with the inputs producing them is imperative for facilitating debugging. Lastly, monitoring and documentation correspond with helping best practices: \textit{Continuously Monitor the Behaviour of Deployed Models} and \textit{Communicate, Align, and Collaborate With Others} respectively.
|
||||
|
||||
To allow customising the service's behaviour to fit different use cases, the default configurations can be overridden by calling some library functions. An example of this can be seen in Listing \ref{listing:complex}, while more details of the semantics can be found in the documentation\footnote{\href{https://great-ai.scoutinscience.com/how-to-guides/create-service/}{great-ai.scoutinscience.com/how-to-guides/create-service}}.
|
||||
To allow customising the service's behaviour to fit different use cases, the default configurations can be overridden by calling some library functions. An example of this can be seen in Listing \ref{listing:complex}, while more details of the semantics can be found in the documentation\footnote{\href{https://great-ai.schmelczer.dev/how-to-guides/create-service/}{great-ai.schmelczer.dev/how-to-guides/create-service}}.
|
||||
|
||||
\subsection{Summary}
|
||||
|
||||
|
|
|
|||
|
|
@ -53,7 +53,7 @@ For the first iteration, 1500 sentences were selected for two experts to annotat
|
|||
\label{fig:scibert-confusion}
|
||||
\end{figure}
|
||||
|
||||
The next step is fine-tuning SciBERT with the help of Hugging Face \texttt{transformers} \cite{wolf2019huggingface}. The data are divided into training and test splits with a ratio of 4:1. A validation split, used for early stopping, is also derived from the train split. The objective function is the F1-score of the positive class, and the early stopping patience is five epochs. The learning rate is $5 \times 10^{-5}$ and AdamW \cite{loshchilov2017decoupled} is used for optimisation with a weight decay of 0.05. The code can be found in the documentation\footnote{\href{https://great-ai.scoutinscience.com/examples/scibert/train/}{great-ai.scoutinscience.com/examples/scibert/train}}, it is surprisingly slightly shorter than the code of Section \ref{section:simple-case}.
|
||||
The next step is fine-tuning SciBERT with the help of Hugging Face \texttt{transformers} \cite{wolf2019huggingface}. The data are divided into training and test splits with a ratio of 4:1. A validation split, used for early stopping, is also derived from the train split. The objective function is the F1-score of the positive class, and the early stopping patience is five epochs. The learning rate is $5 \times 10^{-5}$ and AdamW \cite{loshchilov2017decoupled} is used for optimisation with a weight decay of 0.05. The code can be found in the documentation\footnote{\href{https://great-ai.schmelczer.dev/examples/scibert/train/}{great-ai.schmelczer.dev/examples/scibert/train}}, it is surprisingly slightly shorter than the code of Section \ref{section:simple-case}.
|
||||
|
||||
\begin{displayquote}
|
||||
\textbf{Utility of LargeFiles} For the purposes of the documentation, the fine-tuning was conducted in the Google Colab online environment, which is excellent for providing anyone with GPU time for free. However, notebook environments are ephemeral, resulting in the need to manually upload and download all relevant data whenever a new virtual machine instance is granted. The \texttt{LargeFile} implementation alleviated this problem by automatically handling the uploads and downloads. Of course, first, backwards compatibility had to be solved for Python 3.7, the only available environment in Colab.
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Reference in a new issue